Miaosen Chai
I'm an incoming PhD student at
Previously, I received my B.S. in Computer Science from
In industry, I spent some time as a researcher at
Feel free to reach out if you want to chat! |

|


News
|
Research (* indicates equal contribution) |
|
Dual Exam: Controlled Evaluation of Multimodal Agents and World Models XGEN Labs (83 authors, including Miaosen Chai) Preprint arXiv / Website / BibTeX A paired benchmark that evaluates multimodal agents under fixed environment responses and world models under fixed action interventions across physical, digital, social, and scientific domains, revealing uneven task performance and failures to preserve task-relevant state. |
|
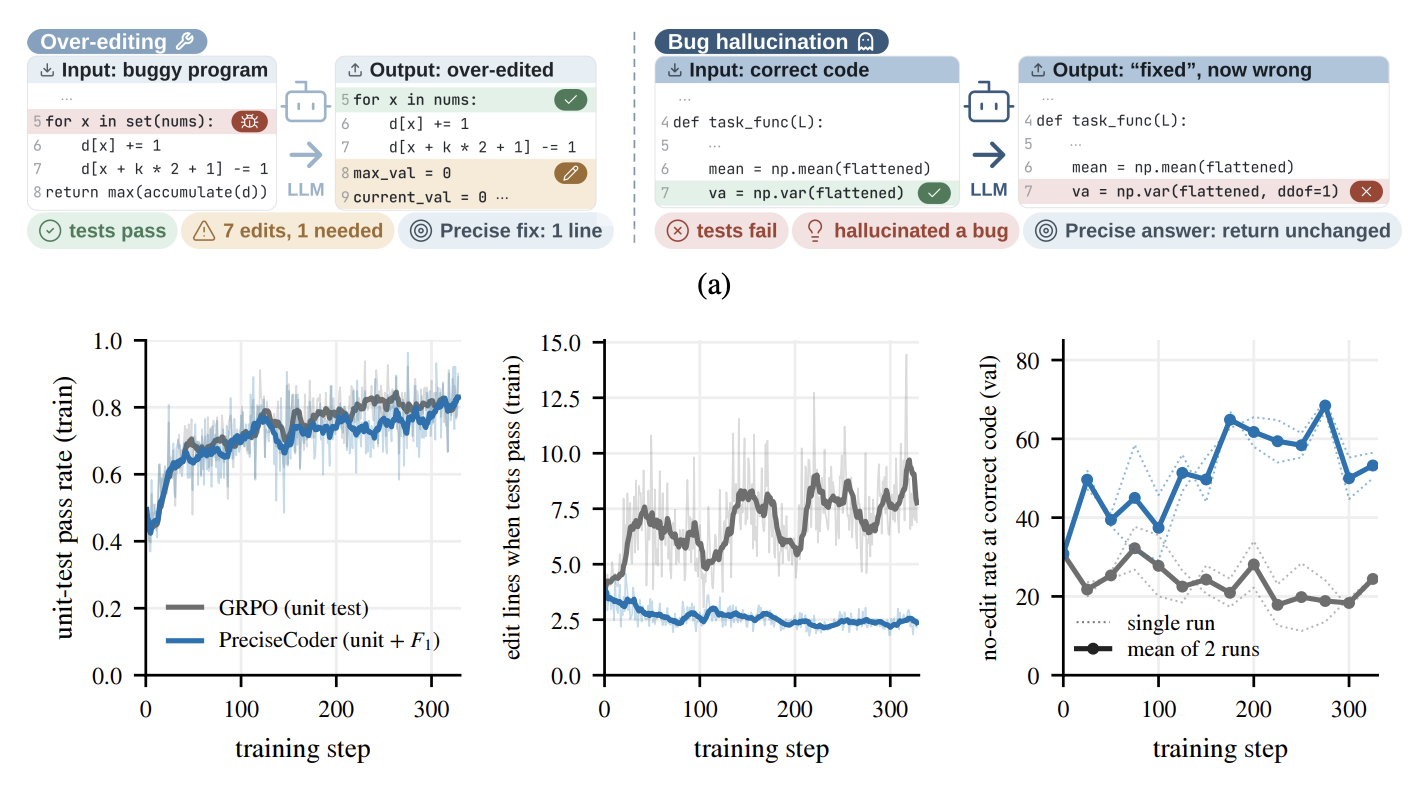
PreciseCoder: Faithful and Generalizable Debugging Beyond Unit-Test RewardsYunkai Zhan, Miaosen Chai, Shangshang Wang, Jike Zhong, Yuqing Yang, Deqing Fu, Serina Chang, Wang Bill Zhu Preprint arXiv / Code / Model / Website / BibTeX PreciseCoder trains debugging models with RL using an edit-level F1 reward alongside unit tests, yielding faithful minimal fixes instead of over-editing, while preserving pass rate and generalizing beyond the training distribution. |

|
Precise Debugging Benchmark: Is Your Model Debugging or Regenerating?Miaosen Chai*, Wang Bill Zhu*, Shangshang Wang, Yejia Liu, Song Bian, Honghua Dong, Willie Neiswanger, Robin Jia NeurIPS 2026 Evaluations and Datasets arXiv / Code / Website / BibTeX A plug-and-paly data engine and benchmark for distinguishing whether a model truly debugs an existing program or simply regenerates it, disentangling repair capability from code generation with new edit-level metrics. |

|
PSALM-V: Automating Symbolic Planning in Interactive Visual Environments with Large Language ModelsWang Bill Zhu, Miaosen Chai, Ishika Singh, Robin Jia, Jesse Thomason ICRA 2026 arXiv / Website / BibTeX PSALM-V automates the induction of symbolic planning models directly from interactive visual environments, letting LLM-driven agents plan reliably without hand-crafted symbolic language for robotics. |

|
Exploring Scientific Hypothesis Generation with MambaMiaosen Chai*, Emily Herron*, Erick Cervantes, Tirthankar Ghosal NLP4Science @ EMNLP 2024 Anthology / Code / BibTeX An early exploration of state-space models for open-ended scientific hypothesis generation, examining how Mamba compares to transformer baselines on grounded scientific text. |